Introduction
An editor at Commonlight needs a usable photo catalog, beginning with a small page sample. You will request real HTTP JSON, select records by their fields and save a CSV. Commonlight is an original local demonstration API: its records and credits are fictional, and its sample pictures are synthetic illustrations, not documentary photographs or an external photo service.
You need Python functions, collections, loops, exceptions and basic file output. HTTP, URLs, JSON and CSV are introduced here. In WebIDE, choose Terminal → New Terminal (the Terminal menu may be under More on a narrow screen). All terminal commands run there. Use Web 8080 for the prepared website. Only edit client.py and storage.py; use the standard library and helper functions defined inside those files, with no additional helper modules/resources. Deliver CSVs as actual ordinary workspace files, not symbolic links; keep catalog.py and /opt/commonlight unchanged. Reading/practice time is an author estimate of 40 minutes, not a measured beginner time.
Request and Understand One Catalog Page
In this step, match three API records to three visible cards, then implement the request function. Switch to Web 8080. The Harbor walks preview contains Morning, market, Blue hour and Window light. It explicitly shows one page, not the entire collection. The pictures provide context; this course exports metadata rather than downloading pictures.
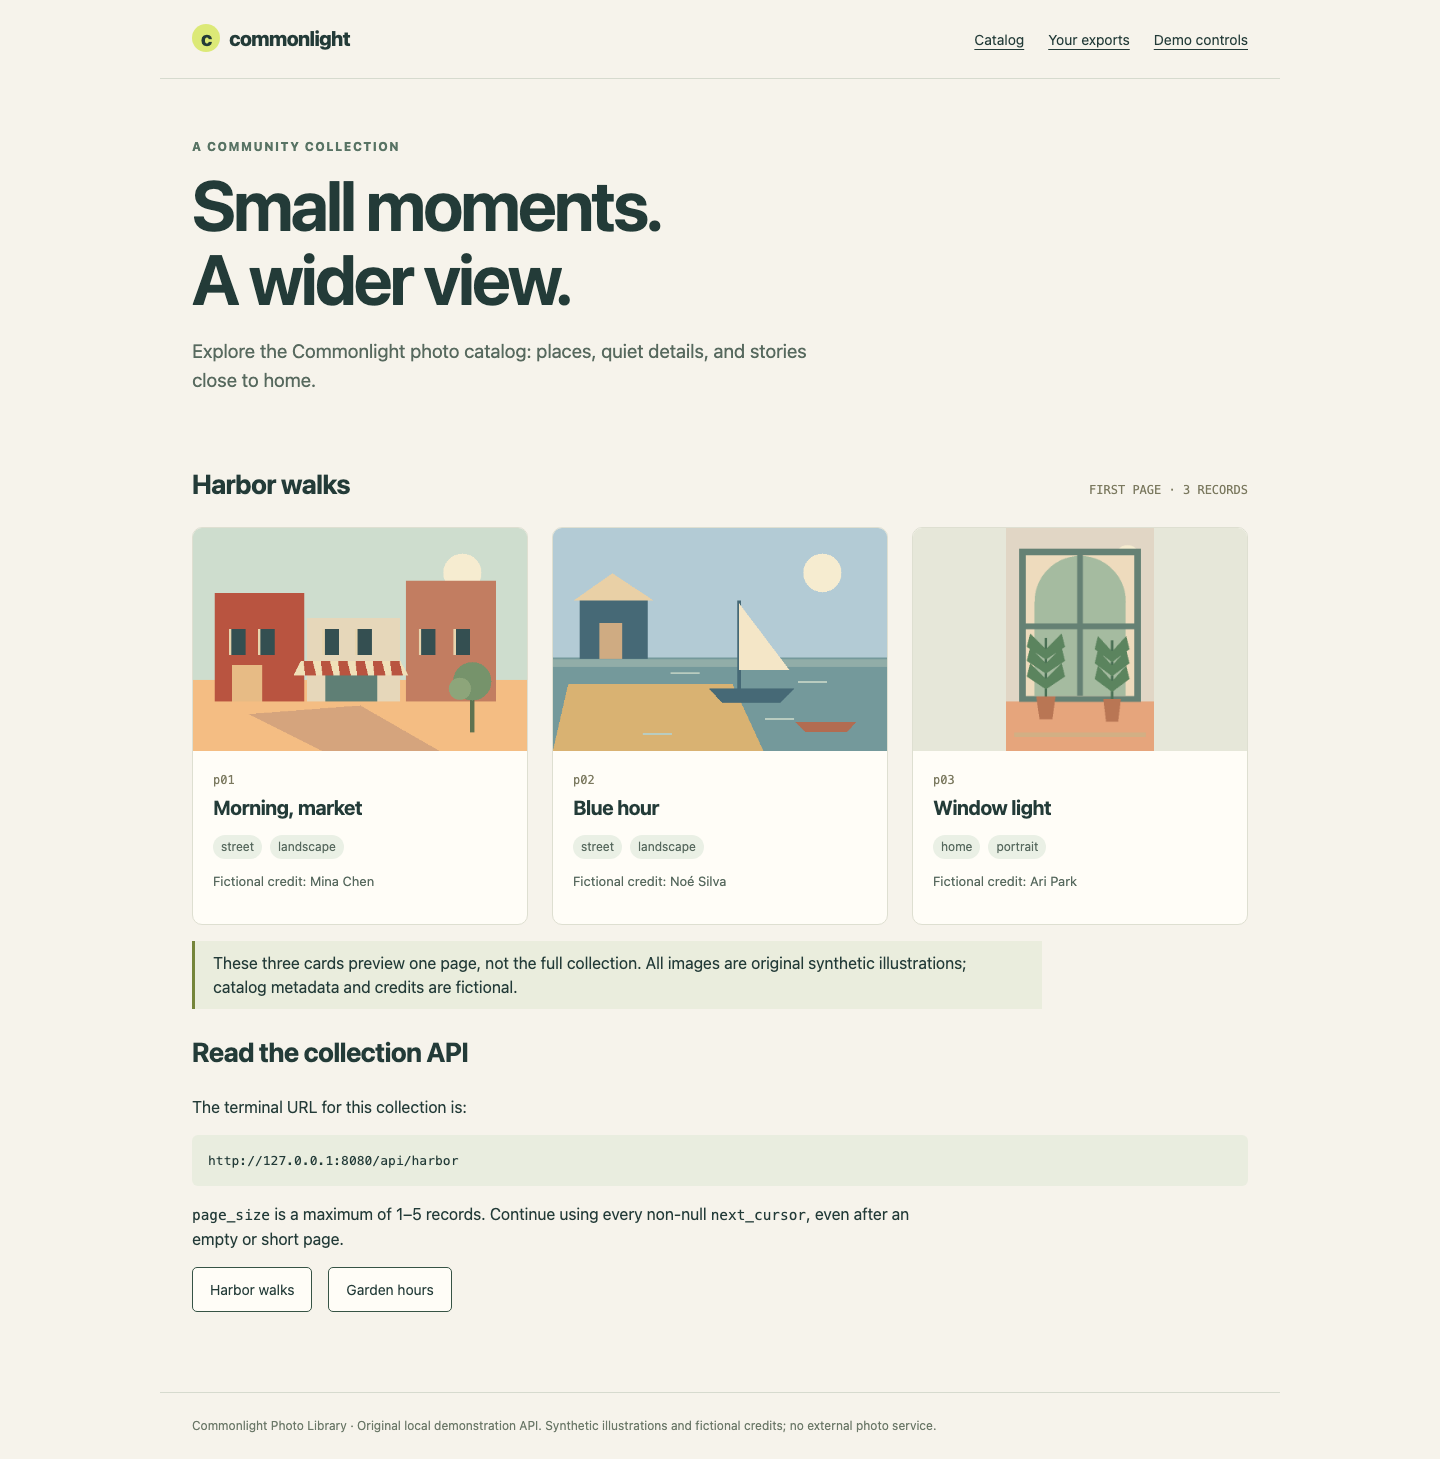
Match the IDs below the artwork with the response you are about to request.
Return to WebIDE and its terminal. cd changes the working directory; python3 runs Python. Use the exact path:
cd /home/labex/project
HTTP is the request/response protocol used by this local API. A URL identifies its address: http is the protocol, 127.0.0.1 is this environment itself, 8080 is the service port and /api/harbor selects a collection. After ?, the query page_size=3 asks for at most three records. The address is for terminal use; Web 8080 opens the platform's browser address for the same service.
The following here-document runs a small Python program. <<'PY' passes the literal lines up to the closing PY to Python's standard input; include both delimiter lines when copying. urlopen sends a real HTTP request. timeout=3 limits blocking operations such as connecting or waiting on a socket, not the duration of every possible complete job. with closes the response afterwards. JSON is structured text; json.load decodes the response into Python data.
python3 - <<'PY'
import json
from urllib.request import urlopen
with urlopen('http://127.0.0.1:8080/api/harbor?page_size=3', timeout=3) as response:
    print('HTTP status:', response.status)
    page = json.load(response)
for photo in page['items']:
    print(photo['photo_id'], photo['title'])
print('More pages:', page['next_cursor'] is not None)
PY
HTTP status: 200
p01 Morning, market
p02 Blue hour
p03 Window light
More pages: True
Status 200 means the request succeeded. The outer JSON object becomes a dictionary. Its items value is a list of record dictionaries; it is not the whole response. JSON null becomes Python None. Here next_cursor is still a string, so more pages exist. This unit deliberately exports one page; the next unit completes traversal.
Each record has photo_id, title, category, orientation and credit. A stable ID identifies a record; its title is a display label and can be shared by different photos. The prepared contract is readable at /opt/commonlight/api-contract.md. cat displays a text file:
cat /opt/commonlight/api-contract.md
Add reusable request and selection functions. urlencode encodes a dictionary into a query string. A cursor is an opaque continuation token: copy it exactly, never guess a number or interpret its characters. The optional cursor=None argument means the first request omits that query parameter. Later pages may contain characters such as +, / and =, which need encoding. Keep the URL and page size unchanged within one traversal.
The selection compares both category and orientation exactly and case-sensitively. No matches is a valid empty list. In the list comprehension, for photo in photos visits each record; if keeps only records satisfying the filter; and requires both comparisons to be true. The result is a new list without changing the received records.
The next block uses cat with > to replace client.py with the literal Python text. Run the complete block including the closing PY. You can also open the file in WebIDE, replace its contents and save it with Ctrl+S (Cmd+S on macOS). This is the only file changed by this block.
cat > client.py <<'PY'
"""The request and selection functions are completed in the first guided lab."""
import json
from urllib.parse import urlencode
from urllib.request import urlopen

def request_page(endpoint, page_size, cursor=None):
    params = {'page_size': page_size}
    if cursor is not None:
        params['cursor'] = cursor
    with urlopen(endpoint + '?' + urlencode(params), timeout=3) as response:
        return json.load(response)

def select_photos(photos, category, orientation):
    return [photo for photo in photos
            if photo['category'] == category and photo['orientation'] == orientation]
def collect(endpoint, page_size):
    return request_page(endpoint, page_size)['items']
PY
The prepared command interface calls these functions. For now, collect is explicitly a one-page starter. Your self-check tests the request against a separate real local HTTP source, so it needs the supplied URL rather than a fixed catalog response. It does not create your CSV for you.
If a command says it cannot open a Python file, display the current directory with pwd and the filenames with ls, return to /home/labex/project using the earlier cd, correct the filename and retry. No VM reset is needed.
Filter a Page and Save a Real CSV
In this step, select the first page's street landscapes and open a CSV containing their real field values. CSV means comma-separated values, but a comma inside a title is part of one field. A proper CSV writer quotes it; joining strings or splitting at every comma loses this relationship. UTF-8 preserves names such as Noé and non-Latin text. newline='' lets the csv module manage CSV line endings.
FIELDS defines the five header names. Each appears once; record and column order may differ in an equivalent solution. DictWriter maps each dictionary value to its named column. writeheader writes that header and writerows writes the selected records, including a header-only file for an empty selection. The file is opened with w, which replaces its contents. This first unit saves a page sample; safe publication of a complete multi-page export comes next.
In the WebIDE terminal, replace only storage.py:
cat > storage.py <<'PY'
"""Single-page CSV writer; safe publication is taught in the second guided lab."""
import csv

FIELDS = ['photo_id', 'title', 'category', 'orientation', 'credit']

def save_csv(output, photos):
    with open(output, 'w', encoding='utf-8', newline='') as stream:
        writer = csv.DictWriter(stream, fieldnames=FIELDS)
        writer.writeheader()
        writer.writerows(photos)
PY
The prepared catalog.py accepts five positional arguments: collection URL, category, orientation, maximum page size and output filename. --first-page explicitly selects sample mode. street and landscape are the two exact filters. Shell quotes keep a URL or a filename together if it contains special characters.
python3 catalog.py 'http://127.0.0.1:8080/api/harbor' street landscape 3 page.csv --first-page
Saved 2 photos to page.csv
Read the result with DictReader, which reconstructs quoted fields. This reads the actual saved file, not the API:
python3 - <<'PY'
import csv
with open('page.csv', encoding='utf-8', newline='') as stream:
    for photo in csv.DictReader(stream):
        print(photo['photo_id'], '|', photo['title'], '|', photo['credit'])
PY
p01 | Morning, market | Mina Chen
p02 | Blue hour | Noé Silva
p03 is absent because it is a home portrait. The comma in the first title and accented credit stay attached to their records.
Now observe an intentional HTTP refusal. The API permits page sizes 1–5, so size 9 returns 400 rather than a successful empty collection. Run this block; its first command is expected to fail. $? is the immediately preceding command's exit status, and printf displays it before another command replaces it.
python3 catalog.py 'http://127.0.0.1:8080/api/harbor' street landscape 9 rejected.csv --first-page
printf 'Exit status: %s\n' "$?"
HTTP request refused: 400. No complete export published.
Exit status: 1
HTTPError represents this HTTP rejection; a connection failure is reported separately as Connection failed. Neither is a legal zero-match result. The prepared command catches the exception to explain it and exits nonzero. Recover by returning to the allowed size; do not change the service:
python3 catalog.py 'http://127.0.0.1:8080/api/harbor' street landscape 3 page.csv --first-page
Switch to Web 8080, choose Your exports, then page.csv. Its table must show the two actual records above. Choose Download CSV and open the downloaded file as text or in a CSV reader. The download contains the saved file bytes; the page does not fetch missing records from the source. Return to Catalog using the page navigation, then switch back to WebIDE for the self-check. You have made a reusable page sample, and the non-null continuation token still tells you it is not a complete catalog.
Summary
You sent real HTTP requests, separated a JSON page envelope from its records, selected exact field values and wrote a correctly quoted UTF-8 CSV. HTTP refusal, connection failure and a valid empty result have different meanings. Your two-record page sample is useful, and the next unit follows the remaining cursors to make a complete export.