Introduction
Field Notes has a partially prepared gallery. One group received a temporary HTTP 503 from its source, while the other groups finished. You will retain that failure evidence, run a new Job with a small retry allowance, and deliver the complete collection without rewriting the already correct JPEGs.
This independent VM includes its own twenty source photographs, shared storage, website, failed Job, and partial outputs. You do not need files from the previous VM. Complete Build the Gallery in Batches first, or be comfortable with its Indexed Job, YAML copy/edit, Pod inspection, and download workflow. The 40-minute duration is an author estimate.
Use Workspace for commands and Gallery for the website. Preserve the supplied files, source and reference images, processor, plan, services, PVC, original first-try Job, and its Pods and logs.
Recover the Failed Photo Group
In this step, connect the incomplete gallery to the native failed index before choosing a recovery policy.
Open Gallery, select Open the gallery, and confirm 14 of 20 images available. The first, third, and fourth groups have finished; the six photographs in group 1 are absent. Open Reference in the page navigation to see the supplied normal example, then switch to Workspace.
The terminal starts at /home/labex/project/photo-gallery. Use pwd to confirm it; if necessary, return with cd /home/labex/project/photo-gallery. Read the group mapping and staff brief:
cat inputs/groups.txt
cat inputs/brief.txt
There are four zero-based groups. Index 1 contains photo-07 through photo-12. Inspect the retained attempt:
kubectl describe job first-try -n photo-workshop
Look for Completion Mode: Indexed, Completed Indexes: 0,2,3, one failed Pod in Pods Statuses, and the FailedIndexes warning under Events. The completed indexes and the Pod table below identify the missing group. Read its policy in the supplied source:
cat starter/first-try.yaml
backoffLimitPerIndex: 0 permits no replacement after a failure in an index. backoffLimit: 6 is a separate global failure budget: it does not override a zero per-index allowance. activeDeadlineSeconds: 180 is the active lifetime limit. The Job remains failed even though several indexes succeeded.
List its actual Pods and their index labels:
kubectl get pods -n photo-workshop -l batch.kubernetes.io/job-name=first-try -L batch.kubernetes.io/job-completion-index
Read all of their logs:
kubectl logs -n photo-workshop job/first-try --all-pods=true --prefix=true
The index-1 Pod reports Source returned HTTP 503 and exits; the other groups report their completed photographs. HTTP 503 means the source answered but was temporarily unavailable. It differs from a missing Pod, connection failure, or unreadable JPEG.
Copy the full index-1 Pod name from the table into the following command, replacing POD_NAME rather than typing the placeholder literally:
kubectl describe pod POD_NAME -n photo-workshop
Its terminated container shows Exit Code: 42. This is the supplied worker's deliberate response to the source HTTP error, not a general Kubernetes HTTP error code. The scenario produces one real 503 for the first request in index 1 of each new Job. The next replacement Pod for that same index can read the source successfully. This is a controlled temporary-failure exercise, not a claim that every production 503 is safely retryable.
Keep the failed Job, its Pods and logs, and the fourteen existing correct JPEGs. The processor writes an identical JPEG only when needed; already matching image bytes and their file metadata are kept. Per-Pod receipts and image index records can be updated to identify the new successful attempt.
Give Each Index a Finite Retry
Now create a new Job with one permitted retry per index. Do not attempt to turn the already failed Job into a new run.
In Workspace, at /home/labex/project/photo-gallery, copy the supplied recovery draft:
cp starter/recovery-job.yaml gallery-job.yaml
As in the previous lab, cp keeps the source intact. If the source cannot be found, confirm pwd, return to the workspace, and repeat the exact copy. Read the draft:
cat gallery-job.yaml
It already requests all four indexes with parallelism 2, but has the draft name gallery-draft and no per-index retries. Use sed -i to replace each literal value in your copied file; single quotes protect the replacement expressions from shell interpretation:
sed -i 's/name: gallery-draft/name: gallery-retry/' gallery-job.yaml
sed -i 's/backoffLimitPerIndex: 0/backoffLimitPerIndex: 1/' gallery-job.yaml
Read the file again:
cat gallery-job.yaml
Confirm name: gallery-retry, completions: 4, parallelism: 2, and backoffLimitPerIndex: 1. Keep backoffLimit: 6, activeDeadlineSeconds: 180, and all supplied processor, mount, identity, and resource settings. This task accepts one or two retries per index, but a small finite allowance is enough. Removing the deadline or allowing unlimited retries would hide a persistent problem.
A new Job has a new Kubernetes identity. It may process groups that succeeded before; the supplied worker handles this repeated execution without rewriting matching JPEGs. Do not infer exactly-once processing from a successful Job. Preserving the old failed Job also keeps the reason for this recovery visible. If an edit did not match, re-copy and correct the draft before applying it. If you already created an unsuitable final Job, keep its evidence and prepare a different new name in the saved file rather than changing an immutable Pod template or deleting first-try.
Apply the saved new Job:
kubectl apply -n photo-workshop -f gallery-job.yaml
Wait for its successful completion:
kubectl wait -n photo-workshop --for=condition=Complete job/gallery-retry --timeout=180s
Inspect its indexes and policy:
kubectl describe job gallery-retry -n photo-workshop
Expect Completed Indexes: 0-3. The preceding wait command has already confirmed the native Complete condition. List the actual Pods:
kubectl get pods -n photo-workshop -l batch.kubernetes.io/job-name=gallery-retry -L batch.kubernetes.io/job-completion-index
Index 1 now has a failed Pod and a different completed replacement Pod for the same index. The failed Pod is expected evidence of this controlled test. Read their output:
kubectl logs -n photo-workshop job/gallery-retry --all-pods=true --prefix=true
You should see the real HTTP 503, then successful processing in its replacement. Other groups report Kept for the JPEGs that already matched. If waiting times out, inspect the new Job and Pod logs; do not erase the old failure, reset setup, or increase retry limits blindly. Requested parallelism is a desired concurrency setting rather than an absolute process guarantee during replacement.
Deliver the Recovered Collection
In this step, prove the retry produced the full usable gallery and save its current downloads.
Switch to Gallery, select Gallery in the page navigation, and refresh. Confirm 20 of 20 images available. Open Black-and-white blossoms (photo-07), the first photograph in the recovered group, and compare it with its own source. Select Download thumbnail and Back to gallery. Also open Blue and yellow flowers (photo-20) from the short final group.
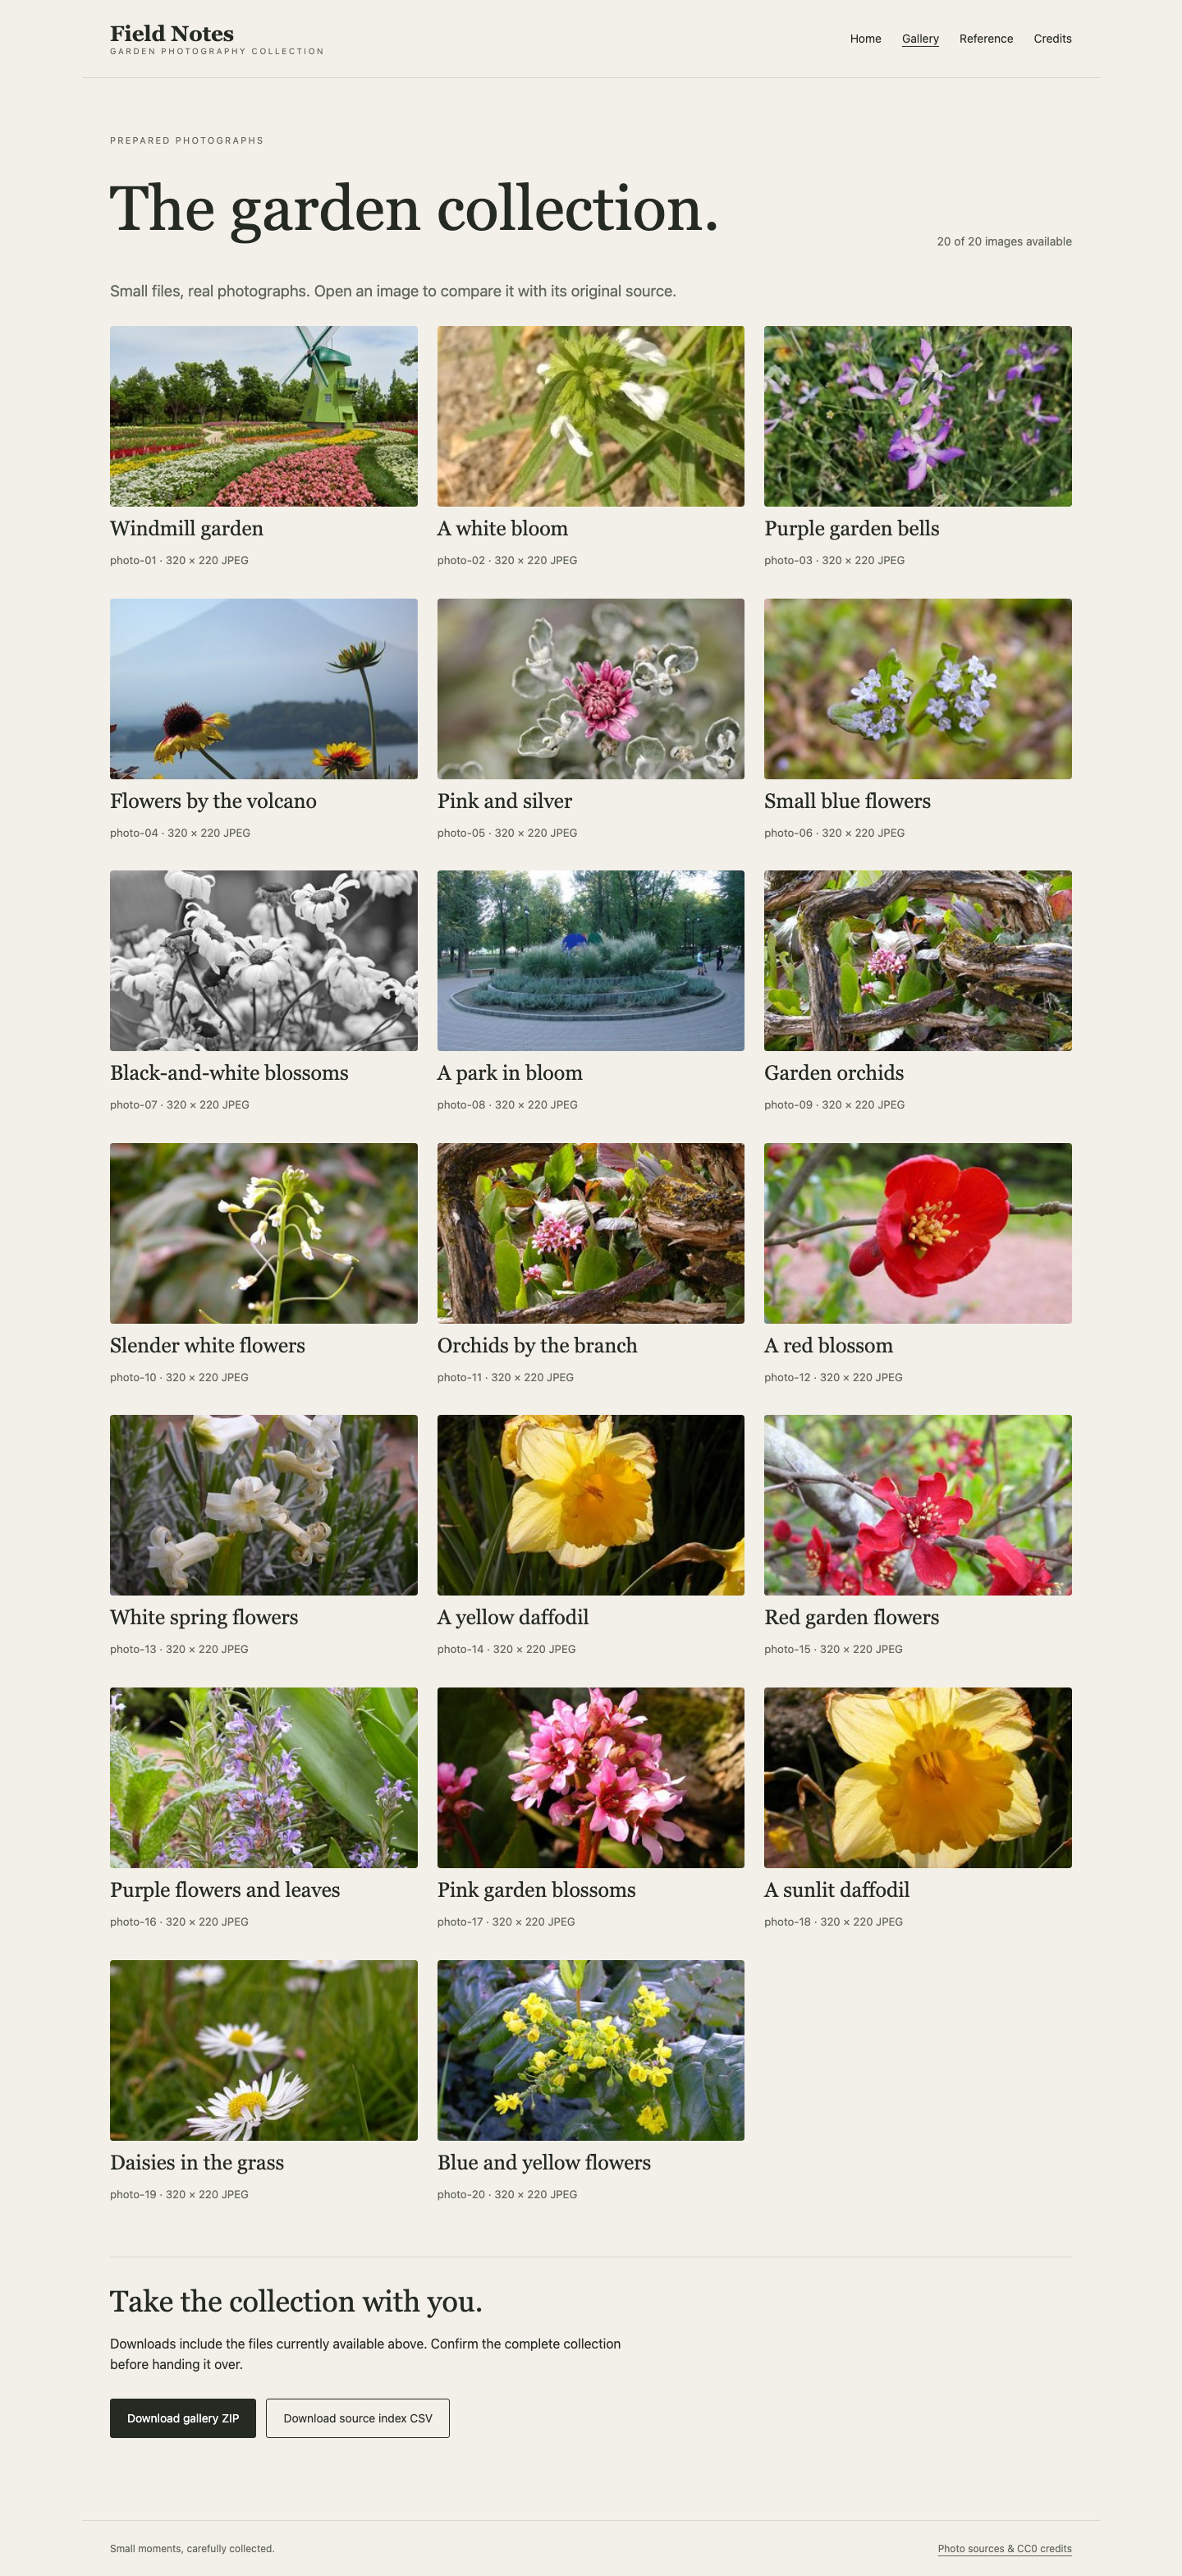
The recovered collection now includes the six missing photographs and the short final group. The page still points to the unchanged reference and licensed sources.
Return to the gallery and use Download source index CSV and Download gallery ZIP. Select Reference to confirm the supplied example remains intact, and Credits to check source attribution. The site only displays actual readable worker output; it does not fill missing images from the source collection.
Switch to Workspace, at /home/labex/project/photo-gallery. Save the current real handover files using the same options taught in the first lab:
curl --fail --silent --show-error http://127.0.0.1:8091/download/index.csv -o gallery-index.csv
curl --fail --silent --show-error http://127.0.0.1:8091/download/gallery.zip -o gallery.zip
Inspect the CSV header and first rows:
head -n 3 gallery-index.csv
List the archive safely without extracting it:
python3 -m zipfile -l gallery.zip
It contains index.csv and twenty actual JPEGs, including the recovered group and photos/photo-20.jpg. The source and thumbnail hashes connect each photograph to its own result; file names alone are insufficient.
Finally confirm both attempts remain available:
kubectl get jobs -n photo-workshop
The original first-try is failed and the new gallery-retry is complete. This is the intended final state. Leave the saved manifest, downloads, successful and failed Pods, original fourteen JPEGs, sources, and reference available. If a download fails or is incomplete, correct the workload or service and download again; do not repair the received files by hand.
Summary
You diagnosed a partial Indexed Job failure, preserved its native evidence, and used a new Job with finite per-index retries to finish the real collection. The source-derived files, original successful JPEGs, running gallery, saved manifest, and handover now agree.